What web scraping is
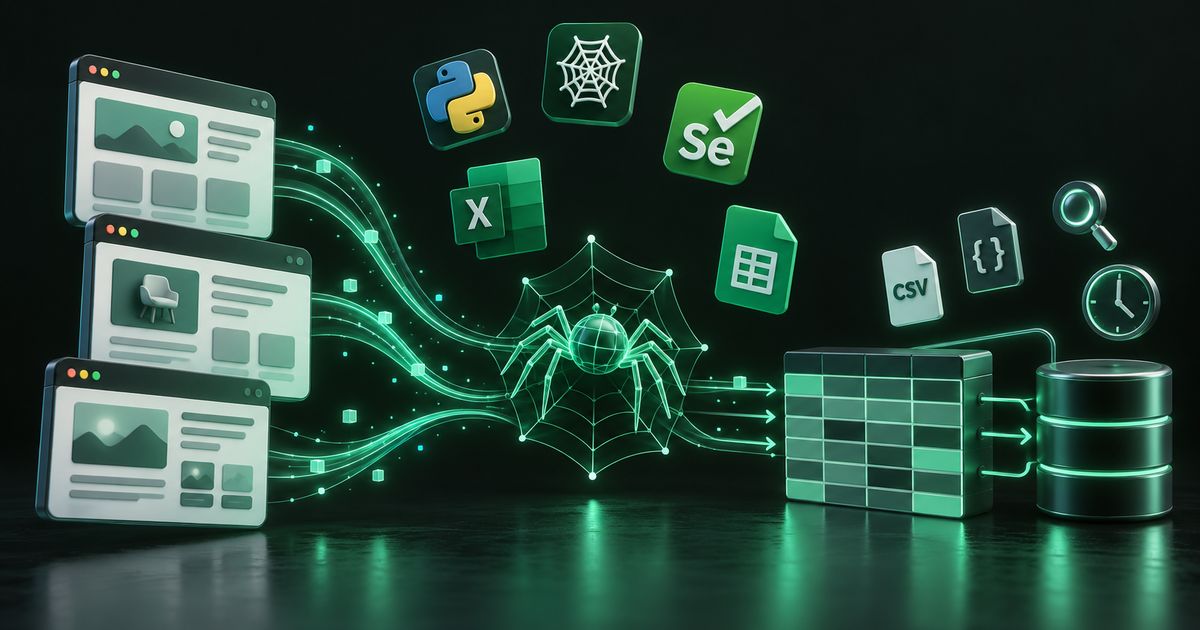
Web scraping is the automated collection of information from web pages. A program visits pages the way a browser would, reads the content, picks out the specific fields you care about — a product’s price, a listing’s location, a company’s industry — and stores them in a structured format such as a database table, CSV file or spreadsheet.
The value is not in the downloading; it is in the structure and the schedule. A person can copy fifty prices into a spreadsheet once. A well-built scraper can check thousands of public product pages every day, record the results as a time series, and alert you when something changes. That turns scattered web pages into a data feed you can analyse and act on.
This guide is for business owners, managers and technical leads considering a scraping or data project. It covers the common use cases, each type of service, how a dependable scraper is built, the tools involved, cost drivers, and — importantly — the responsible and legal limits.
Why businesses invest in web data
Most markets now publish a great deal of useful information openly on the web: prices, catalogues, property listings, product launches, company websites and public registries. Collecting it by hand is slow, error-prone and rarely kept up to date.
- An e-commerce seller tracks competitor prices and stock status so pricing decisions are based on the market rather than guesswork.
- A real estate agency follows how listing prices and inventory move across property portals in the areas it covers.
- A SaaS startup builds a firmographic dataset of companies in its target industry and geography for market sizing and territory planning.
- A distributor keeps its own product catalogue current against supplier specification and availability changes.
- A logistics firm monitors publicly posted tariffs, notices or schedules that affect its operations.
In each case the goal is the same: better decisions from data that is already public but not yet usable.
Web scraping and data services, explained
Scraping projects come in several shapes. The table below summarises each service, and the notes after it explain the details that matter.
| Service | What it delivers | Typical use |
|---|---|---|
| Web scraping | Scheduled, structured collection of public data | Any recurring data feed from websites |
| Data extraction | Specific fields pulled from pages, PDFs or documents | Turning published documents into a dataset |
| Market and company research | Firmographic datasets from public sources | Market sizing, research, territory planning |
| Price monitoring | Price time series with threshold alerts | Competitive pricing decisions |
| Competitor monitoring | Tracked listings, launches and page changes | Keeping up with rivals’ public activity |
| Product data collection | Specs, images, variants and availability | Catalogues, marketplaces, comparison sites |
| Real estate data scraping | Normalised, deduplicated listings over time | Tracking property market movement |
| Custom scrapers | Crawlers for JavaScript-heavy or complex sites | Targets that simple tools cannot handle |
| Data cleaning | Deduplicated, normalised, validated records | Making data trustworthy before use |
| Data processing | Aggregation, enrichment and export | Feeding a database, sheet, CRM or BI tool |
Web scraping and data extraction
Core scraping is a collector that runs on a schedule, follows pagination, respects rate limits and stores results in a queryable form. Data extraction is the precision step: mapping the fields you need into your schema, including awkward cases where layout varies between records. Output should be validated against expected types and ranges, and anything that fails validation should be reported rather than guessed at.
Market and company research
This is company-level research built to your criteria — industry, geography, company size, technology in use — compiled from publicly published sources such as company websites, public registries and open directories. Every record should carry its source URL and collection date so it can be traced. This is firmographic and market intelligence, not personal contact harvesting. Nexon Enterprise does not compile or sell personal contact lists and does not supply data for unsolicited outreach.
Price and competitor monitoring
Price monitoring checks public prices on your schedule and stores them as a time series, so you see trends and not only today’s number. Alerts fire when a price crosses a threshold you set, delivered where you actually read messages — email, a dashboard, or a Telegram bot. Competitor monitoring widens the lens to new listings, launches, pricing page edits and content changes, summarised into something readable rather than raw page differences.
Product and real estate data
Product data collection gathers specifications, images, variants and availability at catalogue scale and refreshes them often enough to stay accurate. Real estate scraping collects listing prices, locations and amenities from property portals and normalises them so records from different sources are comparable. Deduplication matters here, because the same property is frequently listed several times, and historical snapshots let you see how a market is moving.
Custom scrapers
Some public sites render their content with heavy JavaScript or spread it across multi-step navigation. Custom scrapers use headless browsers to handle these cases. Where a login is involved, it should only be an account the client legitimately holds and is permitted to automate under that service’s terms — never someone else’s credentials, and never a way around a paywall or access control. A good provider will tell you plainly if a target is not appropriate to scrape.
Data cleaning and processing
Raw scraped data is rarely ready to use. Cleaning removes duplicates, normalises formats such as currencies, units and addresses, handles missing values explicitly and validates every record against rules you define. Processing then aggregates, enriches from additional public sources and exports straight into your database, Google Sheet, CRM or BI tool on a schedule, with failures alerted instead of silently skipped.
Responsible and legal web scraping
Scraping is a tool, and like any tool it can be used responsibly or irresponsibly. A trustworthy project follows a small number of clear principles.
- Public data only. Collect information that is openly accessible to any visitor without logging in. Do not bypass logins, paywalls, CAPTCHAs or other access controls.
- Respect robots.txt and terms of service. Check the site’s robots.txt directives and its terms of use where applicable, and take them into account when deciding whether and how to collect.
- Rate limiting. Request pages slowly and at sensible intervals, identify the scraper honestly where appropriate, and avoid peak hours for smaller sites. A scraper should never degrade a site for its real users.
- Minimise personal data. Do not harvest personal data — names, phone numbers, email addresses, profiles of individuals — without a lawful basis and a clear, legitimate purpose. Collect only what the purpose actually needs.
- Know the data protection laws. In India, the Digital Personal Data Protection Act, 2023 (DPDP Act) governs the processing of digital personal data. In the European Union, the GDPR applies to personal data of people in the EU, including when processed from outside the EU. Other countries have their own rules.
- Respect copyright and database rights. Collecting facts such as prices is different from republishing someone’s articles, photos or creative work wholesale.
- Keep provenance. Store the source URL and collection date with every record so data can be traced, corrected or removed if needed.
At Nexon Enterprise we apply these principles to every scraping project, and we decline work that relies on bypassing access controls or harvesting personal contact data for unsolicited outreach.
How a reliable scraping project works
- Define the question. Start with the decision the data supports — pricing, market sizing, catalogue accuracy — so only necessary fields are collected.
- Assess the sources. Review each target site’s structure, robots.txt, terms of use and whether the data is genuinely public. Check whether an official API or open data feed exists; if it does, it is usually the better route.
- Design the schema. Agree the exact fields, types, units and identifiers, plus how duplicates across sources will be matched.
- Build the collector. Use the lightest tool that works — plain HTTP requests where possible, a headless browser only where needed — with polite rate limits and retry logic.
- Validate and clean. Check every record against expected formats and ranges; flag anything suspicious.
- Store and deliver. Load results into a database, spreadsheet, API or dashboard in the format your team uses.
- Schedule and monitor. Run on a defined schedule, and alert when volumes drop, fields go empty or errors rise — the usual signs a site has changed.
- Maintain. Websites change their layouts; budget for regular fixes rather than treating the scraper as finished forever.
Tools and technology commonly used
- Languages: Python is the most common choice for scraping and data work; Node.js is also used.
- HTTP and parsing: Requests or HTTPX for fetching pages; Beautiful Soup, lxml or Parsel for parsing HTML.
- Crawling frameworks: Scrapy for large, structured crawls with built-in throttling, retries and pipelines.
- Headless browsers: Playwright or Selenium for pages that render content with JavaScript.
- Data handling: pandas for cleaning and transformation; Pydantic for validation.
- Storage: PostgreSQL, MySQL or SQLite; CSV, Excel or Google Sheets for delivery; object storage for images.
- Scheduling and infrastructure: cron or systemd timers on Linux servers, Docker for packaging, task queues such as Celery for larger jobs.
- Delivery: REST APIs, webhooks, dashboards, email or messaging alerts.
Much of this overlaps with general Python development, and delivering data into other systems often needs API integration.
What drives the cost of a scraping project
- Number of sources. Each website is its own mini-project with its own structure and quirks.
- Site complexity. Static HTML is simpler than JavaScript-rendered pages that need a headless browser.
- Volume and frequency. Hourly checks on many pages need more infrastructure than a weekly run on a few hundred.
- Data cleaning and matching. Normalising and deduplicating across sources — especially property or product matching — takes real effort.
- Delivery format. A CSV file is simpler than a live API, dashboard or two-way CRM sync.
- Monitoring and maintenance. Sites change; ongoing upkeep is a recurring cost that should be planned.
- Hosting. Server and storage costs vary by provider and usage.
See our pricing page for how engagements are typically structured, or contact us with the list of sources and fields you need for a specific estimate.
Common mistakes to avoid
- Collecting everything just in case. More fields mean more maintenance, more storage and more risk. Collect what the decision needs.
- Ignoring official APIs. If a site offers an API or data export, it is usually more stable and more clearly permitted than scraping.
- Scraping too aggressively. High request rates can harm the target site and get your collector blocked.
- No monitoring. Without alerts on volume and completeness, broken scrapers quietly feed bad data into reports.
- Skipping deduplication. Duplicate records inflate counts and distort averages, particularly in property and product data.
- Treating personal data casually. Harvesting contact details without a lawful basis creates legal and reputational risk.
- Assuming it is finished. Every scraper needs maintenance when websites change.
How to choose a web scraping provider
- Do they ask what decision the data supports before quoting?
- Do they check robots.txt, terms of use and whether data is truly public?
- Will they refuse targets that require bypassing logins, paywalls or access controls?
- How do they handle personal data, and do they understand the DPDP Act and GDPR at least at a working level?
- How is data validated, and how are silent failures detected?
- Is the source URL and collection date stored with each record?
- What does maintenance look like when a site changes?
- Will you own the code and the collected data?
A provider who says yes to every target without question is a risk to your business, not a convenience.
Web scraping project checklist
- The business question and required fields are written down.
- Each source has been checked for an official API or data feed.
- Target data is publicly accessible without logging in.
- robots.txt and terms of use have been reviewed where applicable.
- Personal data is excluded, or a lawful basis and purpose are documented.
- Rate limits and schedules are polite and defined.
- The output schema, units and identifiers are agreed.
- Validation rules and deduplication logic are defined.
- Source URL and collection date are stored with every record.
- Monitoring alerts on drops in volume or completeness.
- Delivery format and destination are confirmed.
- A maintenance plan exists for site changes.
How Nexon Enterprise delivers web scraping
Nexon Enterprise is a software, automation and digital-infrastructure company based in Rajkot, India, serving clients in India and abroad. Our web scraping and data solutions cover scheduled collectors, data extraction, market and company research, price and competitor monitoring, product and real estate data, custom scrapers, and cleaning and processing.
We collect publicly available data only, work within robots directives and applicable terms of use, rate-limit politely and keep provenance on every record. Scrapers are built to fail loudly, and they are monitored because sites change. We do not compile personal contact lists, and we will tell you plainly if a target is not appropriate to scrape.
Scraped data often feeds other systems, so these projects frequently connect to our AI and automation and cloud and server work. To discuss a project, contact us with the sources you have in mind and the decisions the data should support.
Frequently asked questions
Is web scraping legal?
Collecting publicly available information is lawful in many situations, but legality depends on the jurisdiction, the data, how it is collected and how it is used. Relevant factors include a site’s terms of use, copyright and database rights, and data protection laws such as India’s DPDP Act 2023 and the EU’s GDPR when personal data is involved. Bypassing logins or access controls, overloading servers or harvesting personal data without a lawful basis create real risk. This is general information, not legal advice; consult a lawyer for your specific case.
Can you scrape data that is behind a login or paywall?
We do not bypass logins, paywalls or other access controls. Where a client legitimately holds an account on a service and its terms permit automated access, working with that client’s own account may be possible, but we assess each case and decline anything that circumvents access restrictions or uses someone else’s credentials.
Do you provide email or phone lists of people?
No. Our market and company research is firmographic — company-level information such as industry, location and size, compiled from public sources with the source recorded. We do not compile or sell personal contact lists, and we do not supply data for unsolicited outreach.
What happens when a website changes its layout?
Layout changes are the most common reason scrapers break. We monitor record counts and field completeness so a change triggers an alert instead of silently producing bad data, and we then update the extraction logic. Planning for ongoing maintenance is part of any realistic scraping project.
How often can data be refreshed?
Anything from hourly to monthly, depending on how fast the market moves and how polite the collection needs to be. Frequent checks on fast-moving prices make sense; weekly runs are often enough for company research or slower property markets. Higher frequency also means more infrastructure and a greater responsibility to rate-limit carefully.
In what format will we receive the data?
Whatever your systems use: CSV or Excel files, a Google Sheet, a PostgreSQL or MySQL database, a REST API, or a direct export into your CRM or BI tool. Alerts for price or competitor changes can be sent by email or messaging apps.
Is it better to use a website’s official API?
Usually, yes. If a site offers an official API or data export, it is typically more stable, more clearly permitted and less work to maintain than scraping. We check for one at the start of every project and recommend it where it covers what you need.
WORK WITH US
Need help with web scraping & data solutions?
Turn publicly available web data into a clean, structured feed — market research, price and competitor monitoring, and custom scrapers that keep running.